
Our own sourcing and follow-up pipeline
The system we use to find practices that fit what we do, screen them, and make first contact, running against our own inbox before it is ever sold to anyone else.
- Status
- Live
- Year
- 2026
- Services
- Slow replies, Manual admin
- Published results
- None yet
The problem
Finding the practices that are a genuine fit for this work is research, and research done by hand is done on the days there is time for it, which is never the busy weeks, which are the weeks it matters. The goal was a pipeline that does the sourcing and the screening continuously, and stops exactly where judgment starts.
How it worked before
- Prospect research was a manual search session, done when there was a gap
- Screening lived in one person's head rather than in written criteria
- Follow-up depended on remembering, so it usually ended after one attempt
- Nothing recorded what had already been checked, so work got repeated
What was in scope.
Deliverables, not outcomes. Anything not on this list was not built, and is not implied to have been.
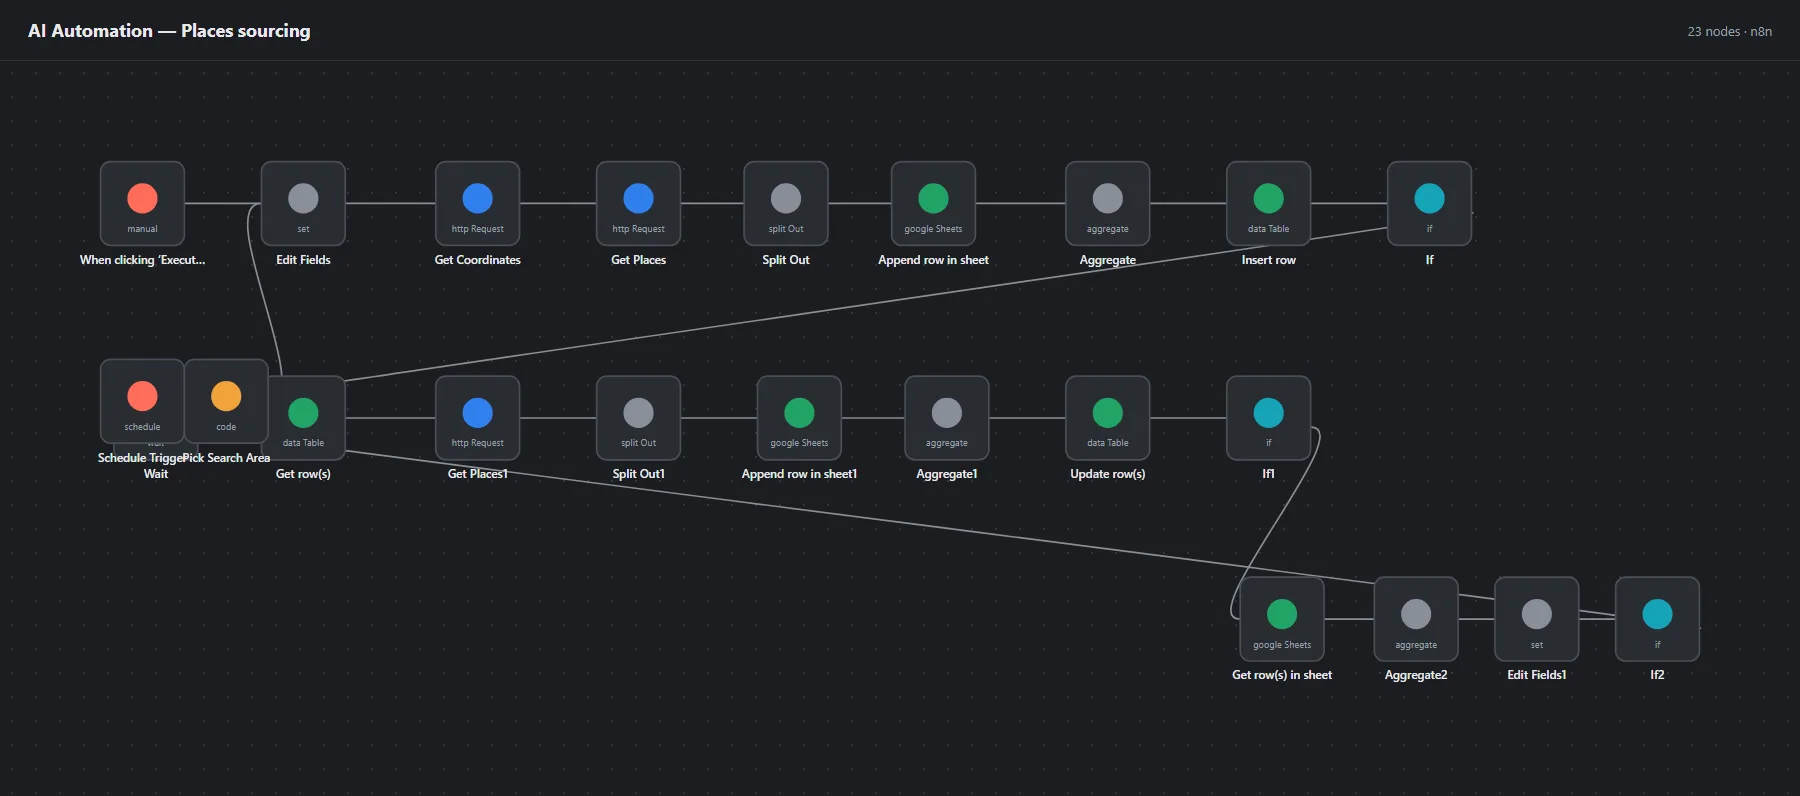
- Sourcing from public business listings
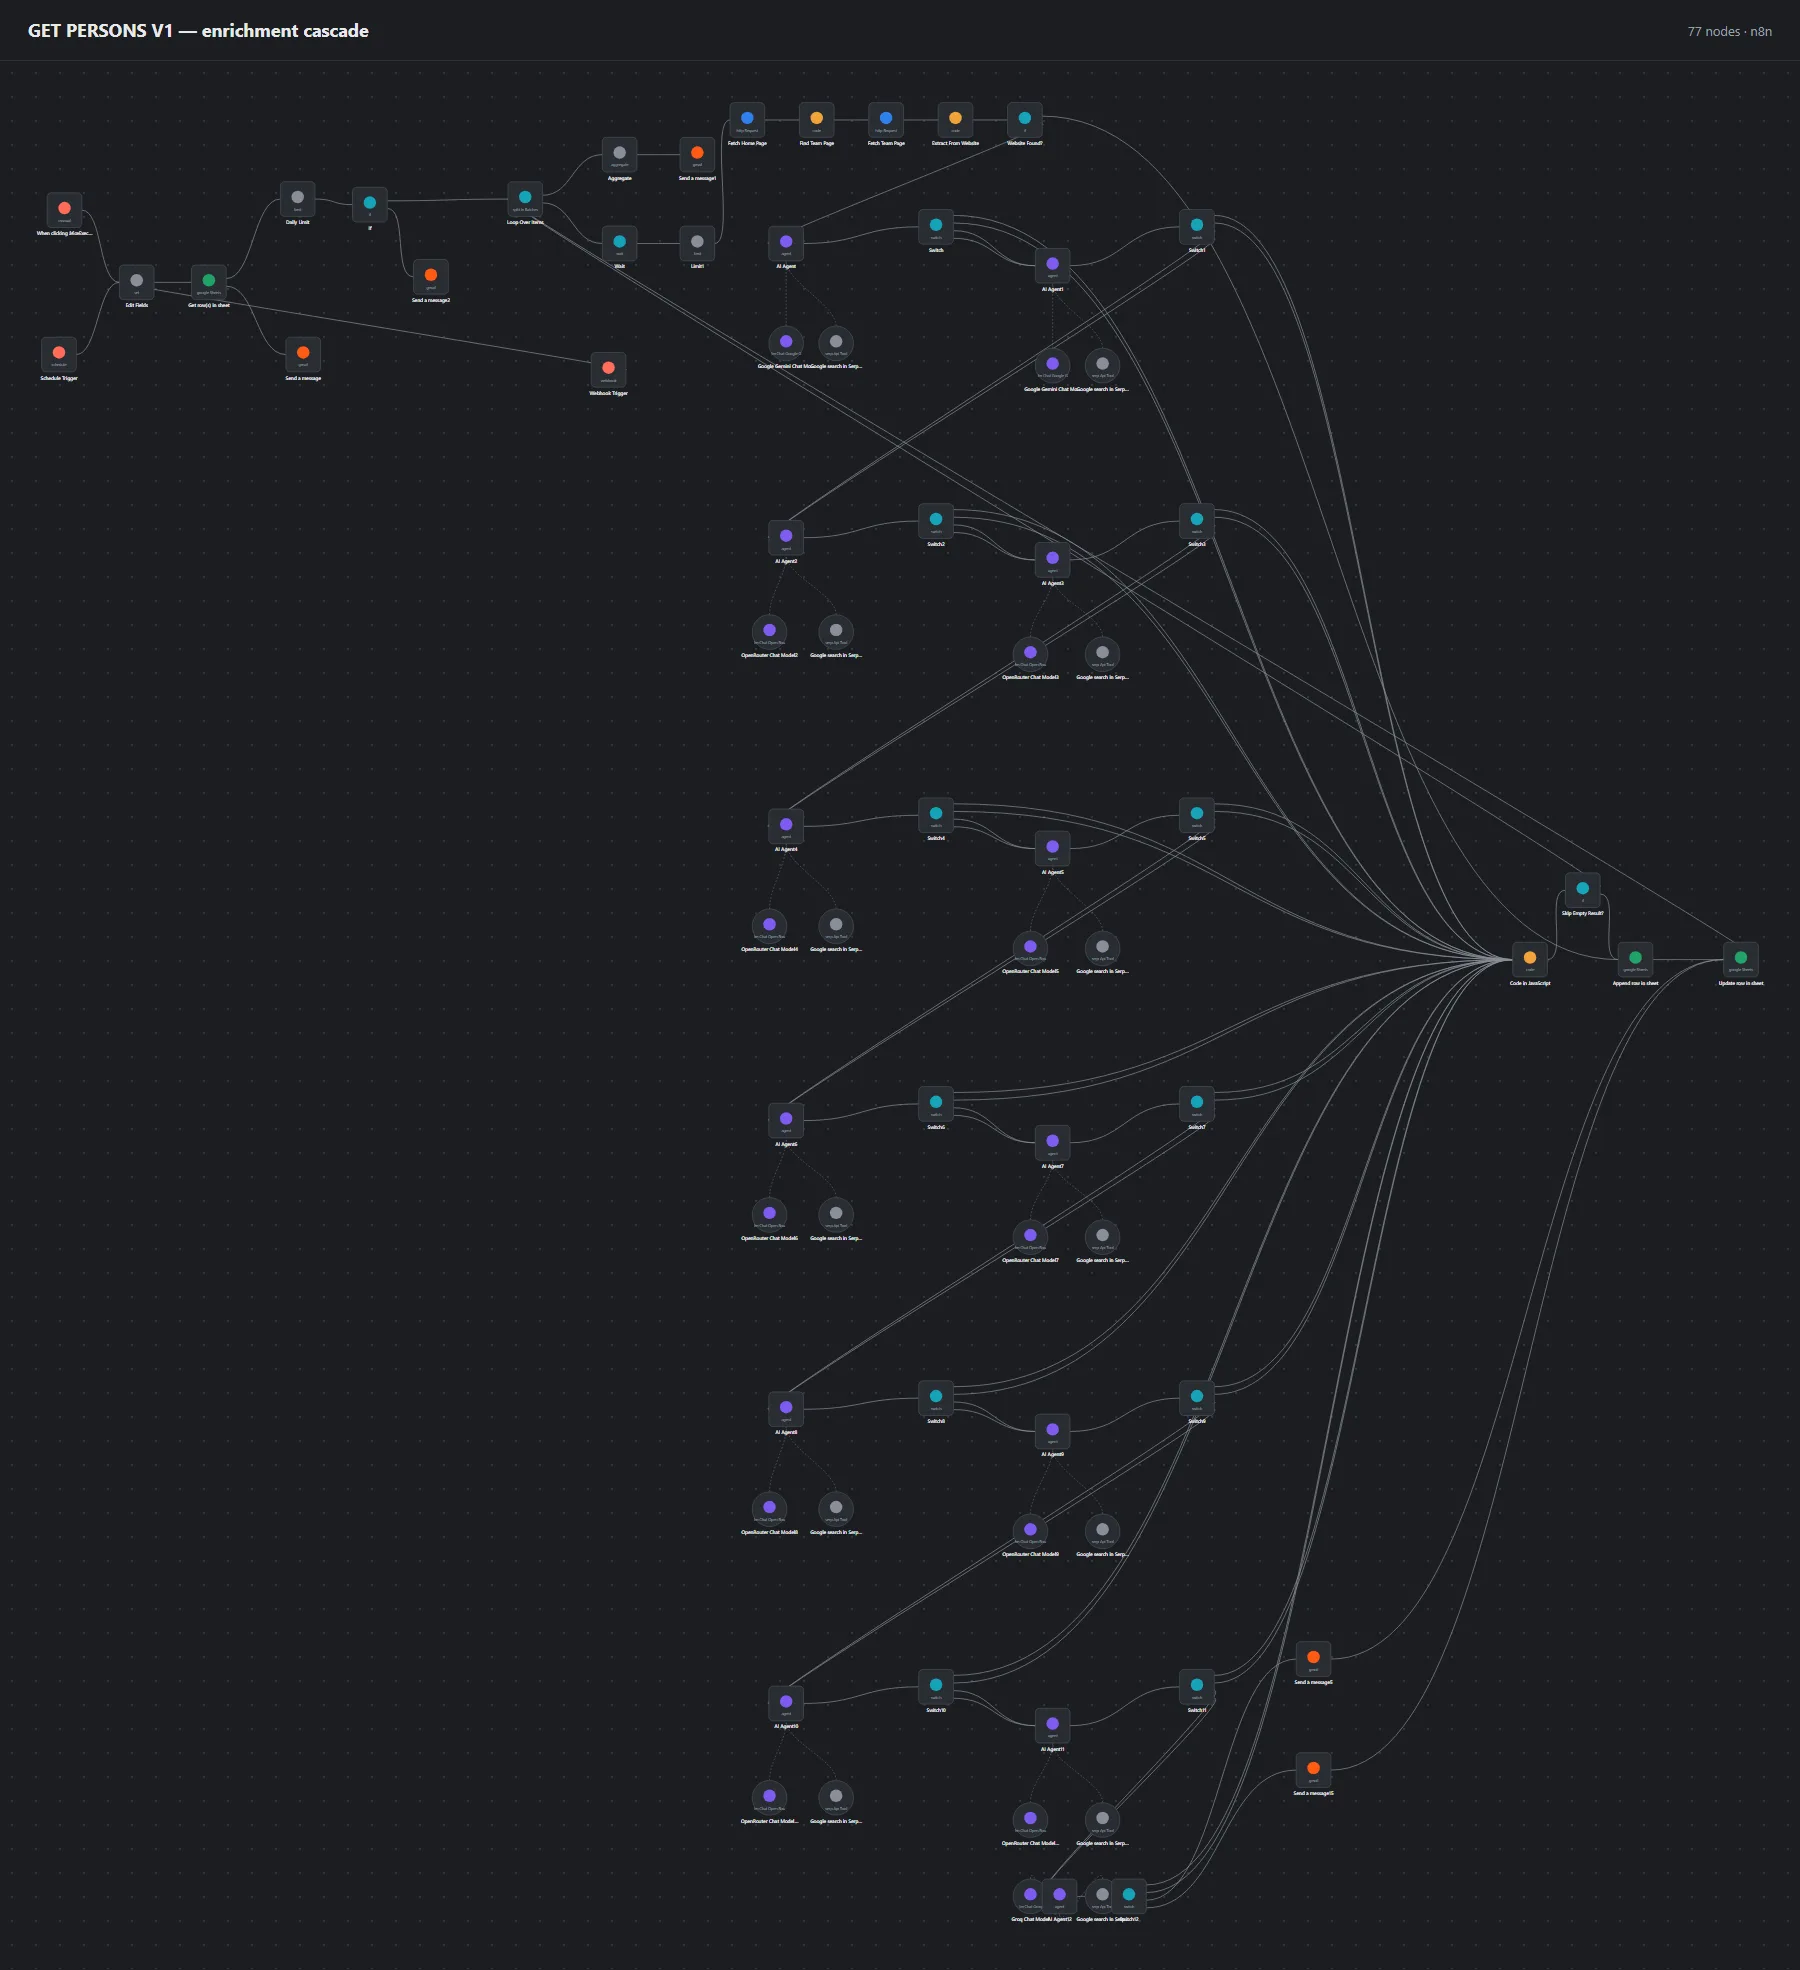
- A multi-stage screening cascade, cheapest checks first
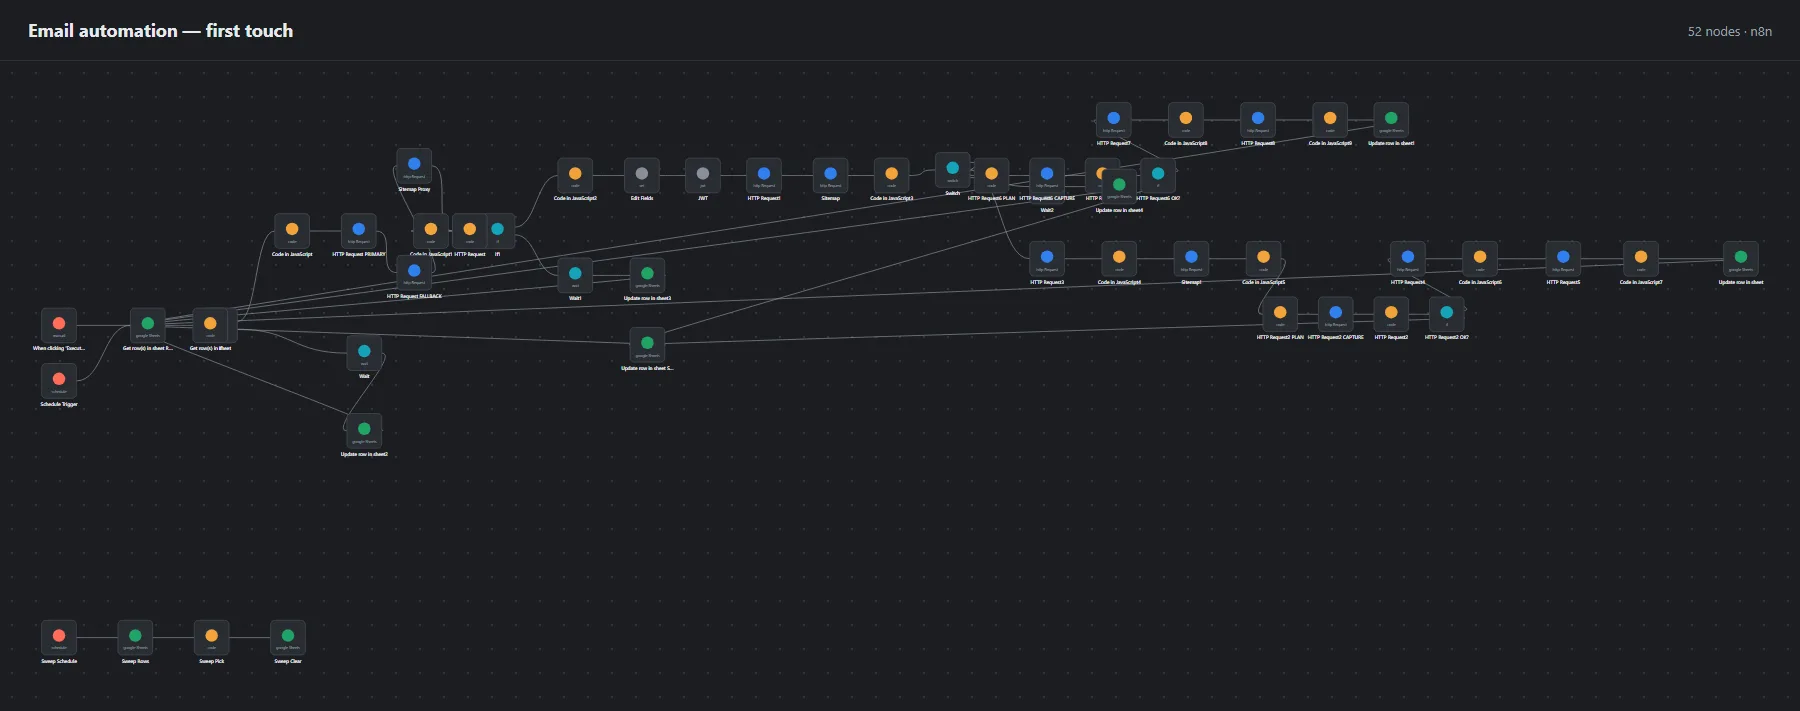
- A drafted first contact that a person reviews before it sends
- Bounce, reply and opt-out handling
- A watchdog that raises a flag when the pipeline stalls or bounces spike
The system, stage by stage.
Each stage does one thing and hands off. The marked stages are the ones a person owns: they are in the diagram because they are part of the design, not because nothing else could reach them.
Sourcing
Candidate businesses pulled from public listings on a schedule, deduplicated against everything already seen.
Cheap checks first
The filters that cost nothing run before the ones that cost a model call. Most candidates never reach an expensive stage.
Enrichment
Public information gathered about the ones that survive the cheap filters.
Screening cascade
Staged assessment against written criteria, each stage able to end the process.
First contact drafted
Written against what the pipeline actually found, not from a template with a name merged into it.
A person decides
Human decisionNothing sends unreviewed. This is the stage the automation exists to protect, not to replace.
Replies, bounces and opt-outs
A reply stops everything scheduled. A bounce and an opt-out are handled differently, and both are recorded.
Watchdog
A separate workflow reading the pipeline's own state on a schedule, alerting when a queue stalls or bounces spike.
One stage in this system is owned by a person. It stops there deliberately: those are the points where being wrong is expensive.
Runs on
Tools you can keep without us.
Everything is set up on your own accounts and your own billing, so the system does not stop working if we do.
- n8nThe workflow layer most of our automation runs on. Self-hostable, which matters when a client wants everything on their own infrastructure.
- OpenAI & Claude modelsUsed at the points in a workflow that need interpretation: reading an unstructured message, summarising a call, classifying a request. Not used where a rule would do.
- Google SheetsUsed honestly: as a queue, a log or a review surface a non-technical person can actually open. Not used as a database.
- Google WorkspaceMail, docs and identity where a business already lives there, which is most of them.
- WebhooksHow one system tells another that something happened, without either polling the other.
- REST & JSON APIsThe documented interface of whatever software you already run. Where one exists, it is how we connect.
These are tools we build with. Braav Labs is not affiliated with, endorsed by or a partner of any of them, and all names belong to their owners.
Why it was built this way.
- 01
We run it on ourselves first
This is the reference build for the response and follow-up systems we sell. Every failure mode we now design around (a queue that silently empties, a provider that rate-limits at the wrong moment, a reply that arrives while a sequence is still running), we hit here first, on our own pipeline, where the cost of getting it wrong is ours.
- 02
The judgment stays human
The system drafts; it does not send unreviewed. Automation handles the sourcing, the qualification and the plumbing between tools. The decision about whether a message is worth sending to a specific practice is still made by a person, because that is the part where being wrong is expensive.
- 03
It watches itself
A separate monitor reads the pipeline's own state on a schedule and raises a flag when something is off: a stalled queue, an unusual bounce rate, a stage producing nothing. A system nobody is watching is a system that has already failed quietly.
- 04
Cheap checks before expensive ones
The order of the qualification stages is a cost decision as much as an accuracy one. Filters that cost nothing run first so that the stages which call a model only ever see candidates that have already survived everything free. Reversing that order is the most common way an automation bill gets surprising.
Results
No measured result yet.
This build has not run long enough to produce a number we can stand behind and show you the source of. When it has, the figure and where it came from go here. We would rather this section say nothing than say something we cannot evidence.
On visual evidence
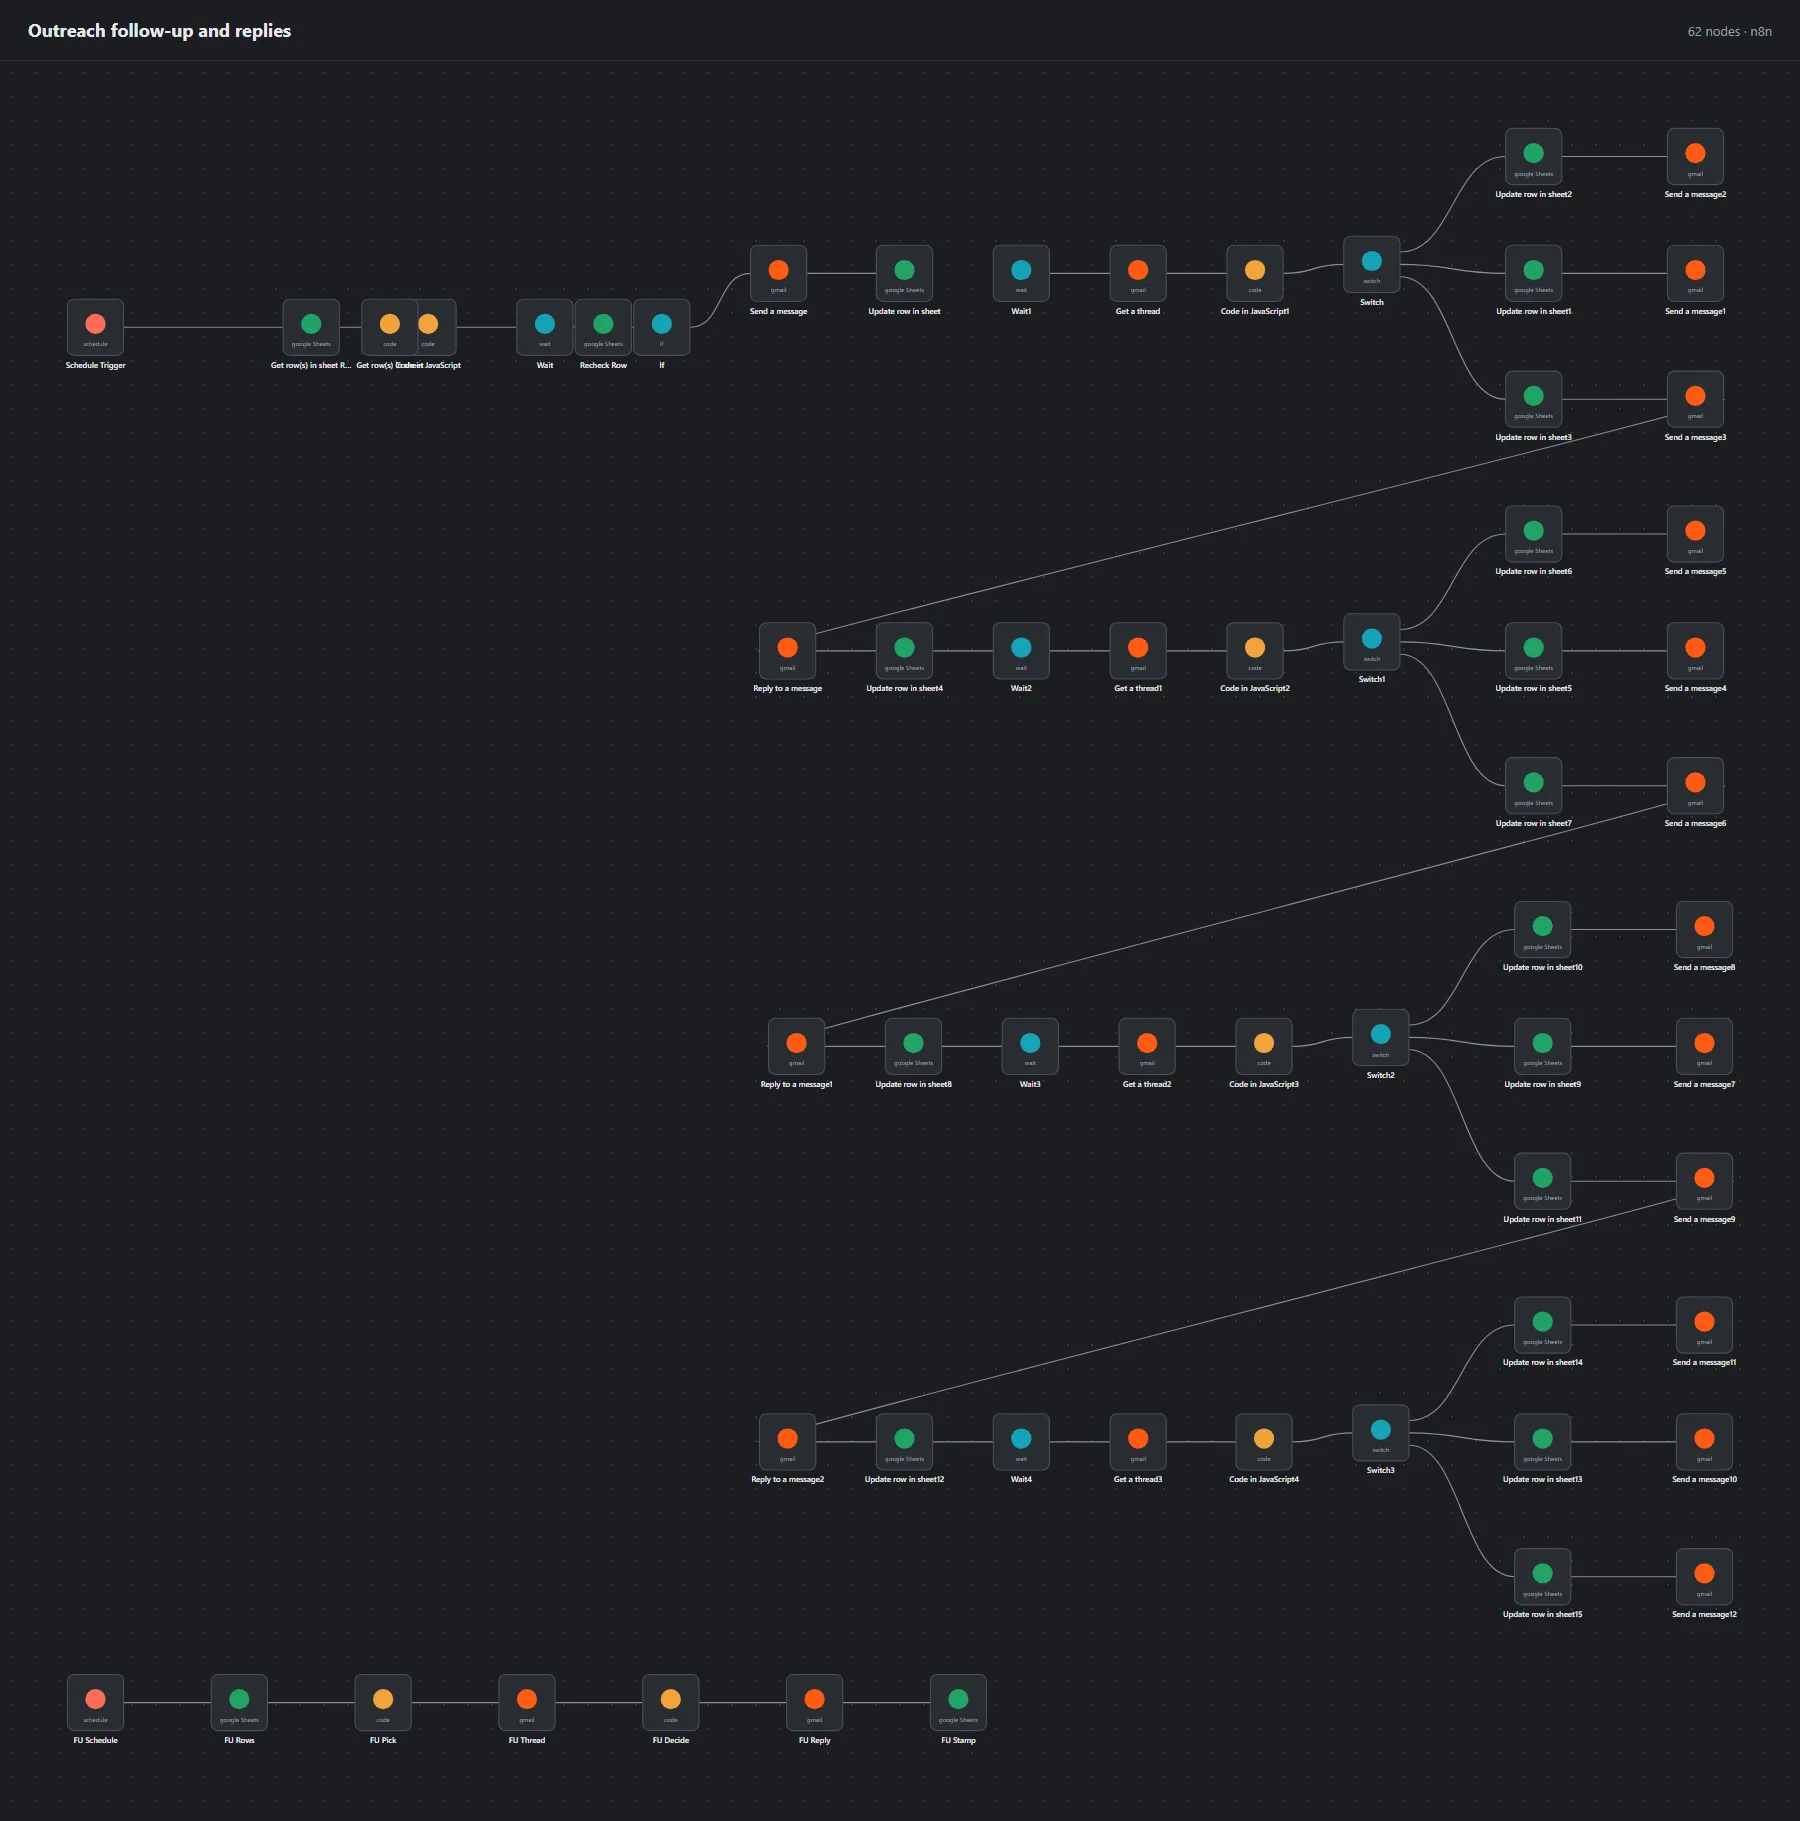
The canvases are drawn from the workflow files in the repositories. Sheet IDs, hosts and addresses are replaced with placeholders.
The code
Read it yourself.
What we would change
What we would do differently.
Written down because the next client gets the version of us that already made these mistakes.
The watchdog should have existed from day one. It was written after a queue had already sat empty for longer than anyone noticed, which is the worst possible time to discover you have no monitoring.
Probing an external site with a command-line tool told us nothing useful: some sites block an automation tool's default user agent while serving a browser fine, so a check that passed by hand failed in the pipeline. The only reliable source of truth turned out to be the pipeline's own execution data.
Early versions moved too much judgment into the automated stages. Pulling the send decision back to a person made the whole thing more useful, not less.
Want something like this built for your business?
Get my free auditOther work
- New-patient website and booking pathA practice site rebuilt around the single question a prospective patient is actually asking (can I be seen, and how soon) with a booking path short enough to finish on a phone in a waiting room.
- Voice agents that play a hard prospectTwo voice agents, a receptionist and an owner, chained into one call so a sales pitch can be rehearsed against a real gatekeeper before it is spent on a real lead.
- Social posts written from cited researchThe system that drafts, renders and queues our own social posts every morning. Every claim comes from a fixed library of cited sources, and nothing posts until a person approves it.
How an engagement runs.
The same five steps whatever we are building, so you always know which one you are in.
- Pricing
- Fixed price, quoted after a scope call
- You have the number before anything is built. Nothing is billed by the hour.
- Timeline
- A date at quote time
- Stated as a commitment, not an estimate that drifts once work starts.
- Ownership
- Everything stays in your name
- Domains, hosting, inboxes and every account, on your billing, documented.
- 01
Scope call
Twenty minutes on how inquiries reach you today. No deck, no discovery package.
- 02
Written scope and a fixed quote
What gets built, when it lands, what it costs. Fixed before anything starts.
- 03
Build and review
You see it working on your own content, not a screenshot of it working.
- 04
Launch and handover
Accounts in your name, a written record of what runs where, a walkthrough.
- 05
Support, if you want it
A separate decision, made after something is already running.
